25 SRE Mock Interview Questions With Sample Answers
Written by Matthew Hale
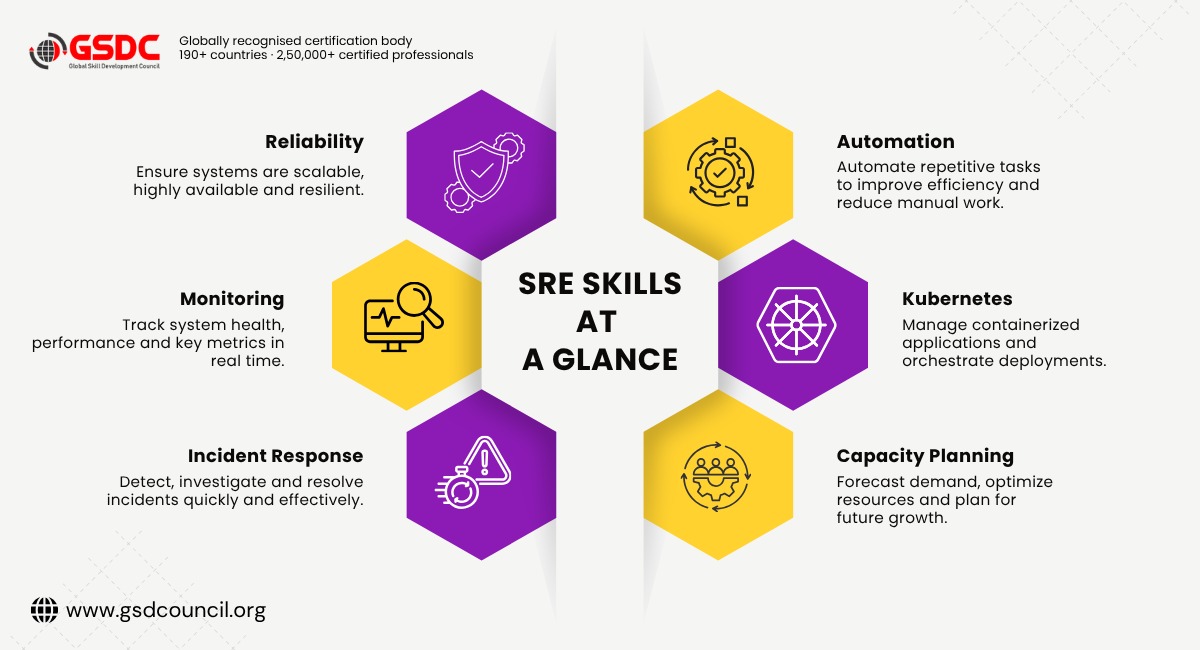
Site reliability engineering moves fast, but reliability, monitoring, incident management and automation stay constant. Mock interview questions are the quickest way to find gaps before a real panel does. This guide covers 25 SRE interview questions and answers, matched to the skills an SRE should know. Sample answers can be adapted with real projects and numbers.
What Is SRE, and Why Do Interviews Test It?
Site reliability engineering (SRE) applies software engineering to operations problems. SRE teams measure reliability, automate repetitive work and use data to decide how fast a product can ship, which is why so many site reliability engineer interview questions focus on SLOs, error budgets, incident response and automation.
SRE roles and responsibilities typically cover monitoring, capacity planning, deployments, incident management and postmortems. SRE best practices such as blameless reviews and small releases come up repeatedly below.
Pay explains why preparation matters. Glassdoor data reported by Coursera puts the average US site reliability engineer salary at about $173,000 a year, so site reliability engineer jobs draw strong competition. For more detail, see this site reliability engineer salary guide. Google's free SRE book and Workbook cover the thinking behind most answers, and a structured SRE course can fill hands-on gaps.
SRE Interview Questions and Answers
1. Explain the relationship between SLI, SLO and SLA.
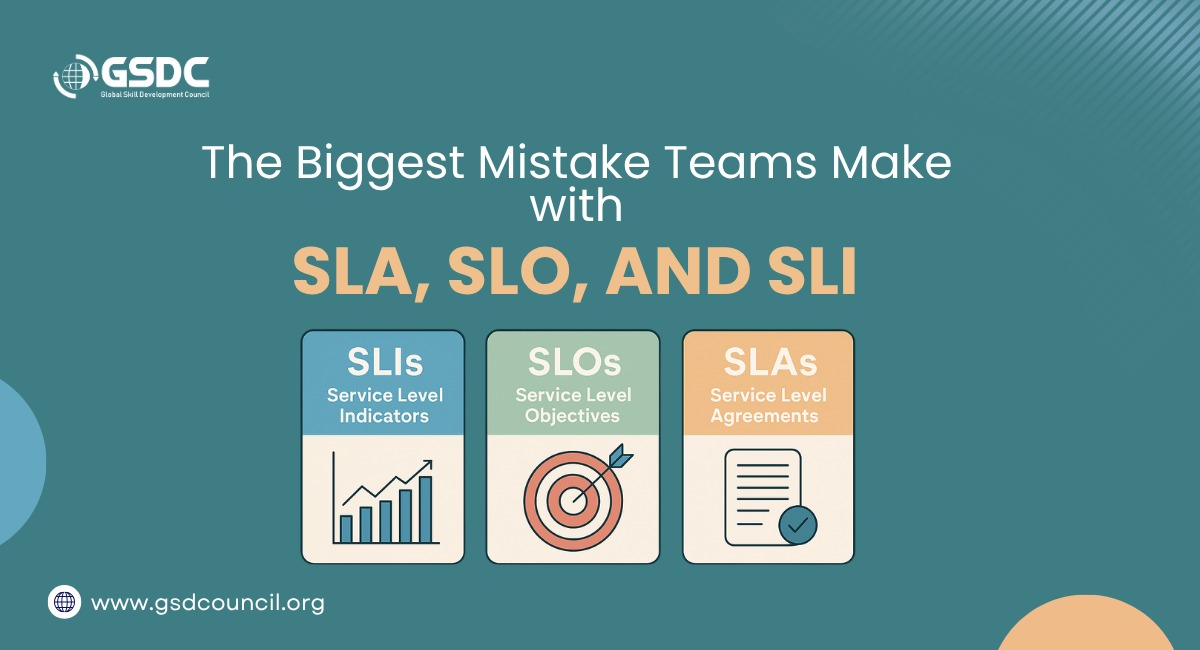
An SLI is a measured indicator, like latency or availability. An SLO is the target for that SLI, such as 99.9% uptime over a month. An SLA is the contract that says what the provider owes, such as credits, if the SLO is missed. For example: the SLI is API response time, the SLO is 90% of requests under 200ms, and the SLA offers a refund if that target is missed.
2. How should a monitoring dashboard for a microservices application be designed?
Show service health and system health together. Core metrics are availability and error rates, latency, throughput, error budget consumption, CPU and memory, service dependencies and key business metrics such as transactions processed. Include real-time and historical views, plus drill-down into individual service failures.
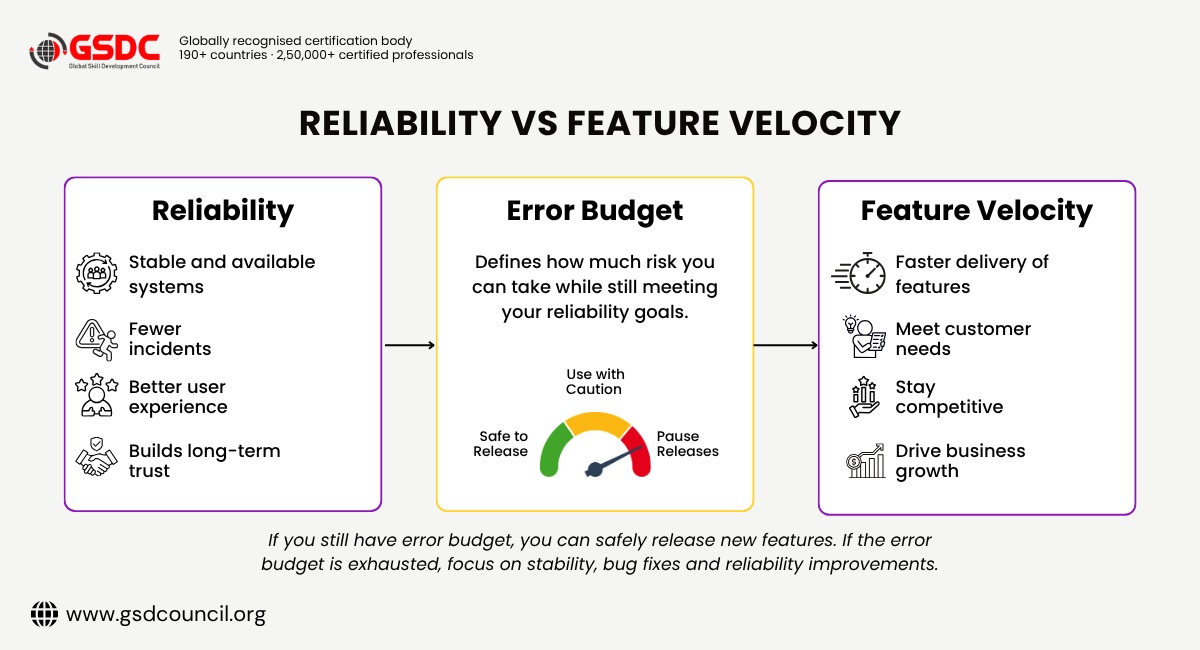
3. How can error budgets influence a release decision?
A critical service had a 99.9% uptime SLO, and rising errors had nearly used up the budget. Releasing more features would have put the target at risk, so the product and engineering teams paused releases until the service stabilized. The time went into bug fixes and performance work so later releases fit inside the budget.
4. How can alert fatigue be reduced in a large environment?
Page only for high-priority issues that need immediate action, using severity levels and thresholds. Group similar alerts, suppress low-impact ones and rate-limit the rest. Add anomaly detection to help judge what is critical, and set escalation policies so alerts reach the right team.
5. How is capacity planning done for a new service?
Estimate traffic from historical data, expected growth and business forecasts. Map dependencies such as databases and third-party APIs, review past CPU, memory and I/O use, and load test with tools like Locust or Apache JMeter. Then calculate redundancy and failover needs. Accurate data on traffic, utilization and failure rates is what makes the plan reliable.
6. Explain root cause analysis after a major incident.
Collect logs, metrics and traces from tools like Prometheus or Azure Monitor, then rebuild the timeline with Jaeger or Grafana. Look for patterns across affected services, work with Dev and Ops on recent changes and isolate the cause, whether it is configuration, network or overload. Finish by documenting findings, shipping fixes and improving monitoring.
There is also a place for structured learning when building SRE skills. A foundation credential such as the Site Reliability Engineering (SRE) Foundation Certification (CSREF) can help organize the core concepts, while practical projects and real incident scenarios turn that knowledge into usable skills.
7. How are blue-green or canary deployments implemented in Kubernetes?
For blue-green, run the new version (green) beside the old one (blue), test it, then switch traffic with a Kubernetes service. For canary, send the new version to a small share of users using rolling updates or Istio traffic management, watch the metrics and scale up only when it is stable.
8. What are the pros and cons of horizontal vs. vertical scaling?
Horizontal scaling adds instances: better availability and fault tolerance, but more complexity and network latency. Vertical scaling adds CPU or RAM to one server: simple, but capped by hardware and a single point of failure. Cloud-native systems usually favor horizontal scaling for redundancy.
9. How are repetitive operational tasks automated?
Identify the repeat work first, such as provisioning, monitoring configuration and incident response. Then use Infrastructure as Code (Terraform, Ansible), CI/CD pipelines (Jenkins, GitLab CI, ArgoCD) and workflow tools like Rundeck, and monitor the automation itself with Prometheus and Grafana. It cuts human error and frees time for strategic work.
10. How is configuration kept consistent across dev, staging and prod?
Define everything as code with Terraform or CloudFormation, keep it in Git, test that configurations deploy consistently and manage environment-specific variables securely with a tool like Vault. Environments stay aligned and release surprises shrink.
11. How are secrets managed in CI/CD pipelines?
Keep secrets out of code. Use a secrets manager such as HashiCorp Vault, AWS Secrets Manager or Azure Key Vault, apply least privilege, encrypt secrets in transit and at rest, and rotate keys and passwords automatically.
12. How are noisy logs handled?
Use structured JSON logging with proper levels (ERROR, WARN, INFO, DEBUG), aggregate logs in the ELK Stack or Splunk, alert only on critical events and set retention policies so logs do not pile up and hurt performance.
13. How can the reliability of a legacy system be improved?
Improving legacy system reliability started with root cause analysis of the latency and downtime. Next came containerizing the app with Docker and splitting out microservices where it made sense. CI/CD and automated tests cut deployment errors, caching and indexing reduced latency by 30%, and Prometheus and Grafana improved incident response.
14. What is chaos engineering, and how should it be introduced?
It means deliberately injecting faults, like server crashes or network latency, to find weaknesses before customers do. Think of it as a fire drill for systems. Start with non-critical services under controlled conditions using Gremlin or Chaos Monkey, monitor closely and run a blameless postmortem after each experiment.
Structured learning can help connect these ideas, especially for engineers moving into SRE from DevOps, software development, or systems roles. GSDC is one of the organizations that covers SRE fundamentals, alongside the hands-on practice that ultimately makes these concepts stick.
15. How are reliability and feature velocity balanced?
Use error budgets: ship while the budget lasts. Pair that with CI/CD and automated testing, small releases that are easy to roll back and a close feedback loop with development teams. Raise reliability early so technical debt gets prioritized next to new features.
16. What is the difference between service discovery and load balancing?
Service discovery lets services register and find each other automatically. Load balancing spreads incoming traffic across them. Together, discovery tells the system what is available and the balancer distributes requests, supporting availability and fault tolerance.
17. Explain least privilege and how it is enforced in the cloud.
Grant only the minimum access needed. Use RBAC and IAM policies in AWS, Azure or GCP, review audit logs regularly and give temporary elevated access (AWS STS or Azure Managed Identity) that is revoked right after the task. It shrinks the attack surface.
18. How is disaster recovery planning approached?
Assess and rank risks, take regular backups with multi-region replication and define the Recovery Time Objective (RTO) and Recovery Point Objective (RPO). Run DR drills and failover tests, and automate restoration with Terraform or CloudFormation.
19. What makes an alert actionable?
A clear description with context, severity levels, remediation steps, aggregation to avoid alert storms and key metrics such as error rate or memory use. These SRE best practices cut diagnosis time and keep on-call focused.
20. How are intermittent network issues diagnosed?
Collect latency, packet loss and throughput metrics, check logs for patterns, try to reproduce the problem with load tests or chaos tools, trace requests with Jaeger or OpenTelemetry and inspect switches, routers and firewalls for congestion or misconfiguration. Then fix the cause and add prevention.
21. What are the main challenges of working with Infrastructure as Code?
Terraform, CloudFormation and Ansible with configs stored in Git keep changes tracked and reversible. The challenges are state management across teams, testing without deploying (isolated non-production environments help) and collaboration (code reviews and documentation help). IaC is a core part of modern DevOps practices.
22. How is resource use managed in containers?
Set CPU and memory requests and limits, use Kubernetes horizontal pod autoscalers, monitor with Prometheus, Grafana or Datadog and tune allocations from historical data to avoid over-provisioning.
23. What does a blameless postmortem process look like?
Gather logs and metrics, rebuild the timeline, find the root cause with 5 Whys or fishbone diagrams without blaming individuals, turn findings into actions on process, automation or monitoring, and share the learnings with relevant teams.
24. How can an SRE keep up with new tools and practices?
Read Google's free SRE book and Workbook, attend SREcon, follow practitioners like Charity Majors and David N. Blank-Edelman, try new tools such as ArgoCD or AI-assisted incident triage, and stay active in communities on Slack, Reddit and GitHub.
25. How can reliability improvements be advocated to stakeholders?
Quantify downtime in lost revenue and customer trust, use MTTR, SLOs and error budgets as evidence, propose concrete fixes like automated testing, canary deployments and better monitoring, and show the ROI in fewer incidents and higher uptime.
SRE Certification: Where It Fits
Interview answers land better when they rest on a structured foundation. For candidates weighing site reliability engineering certification options, the Global Skill Development Council (GSDC) offers the Certified Site Reliability Engineer Foundation, which covers SRE fundamentals behind many of the questions above. Whether an SRE certification is worth it depends on experience and target role, so compare a couple of options against real job listings first.
Wrapping Up
Preparing for an SRE interview takes more than technical knowledge. It calls for problem-solving, clear communication and a working sense of how reliability and scalability fit together. Practice these mock interview questions for SRE out loud, and the answers will sound natural in the real thing.

Related Certifications
Frequently Asked Questions
SRE applies software engineering to operations so systems stay reliable, scalable and efficient. Google created the approach and documented it in its SRE book.
Monitoring and alerting, incident response, capacity planning, safe releases, automation and blameless postmortems.
The average US SRE salary is about $173,000 a year according to Glassdoor data reported by Coursera, and it varies with experience, employer and location.
It can help early in a career or when moving over from sysadmin or DevOps work. More experienced engineers may look at a practitioner-level option such as the Certified SRE Practitioner.
Stay up-to-date with the latest news, trends, and resources in GSDC
If you like this read then make sure to check out our previous blogs: Cracking Onboarding Challenges: Fresher Success Unveiled
Not sure which certification to pursue? Our advisors will help you decide!